Hello, friends, many of you know that I use Bash every day. Many assume that is because I mainly do GNU / Linux system administration, but they are wrong… I use bash daily in very different contexts.
Demonstration
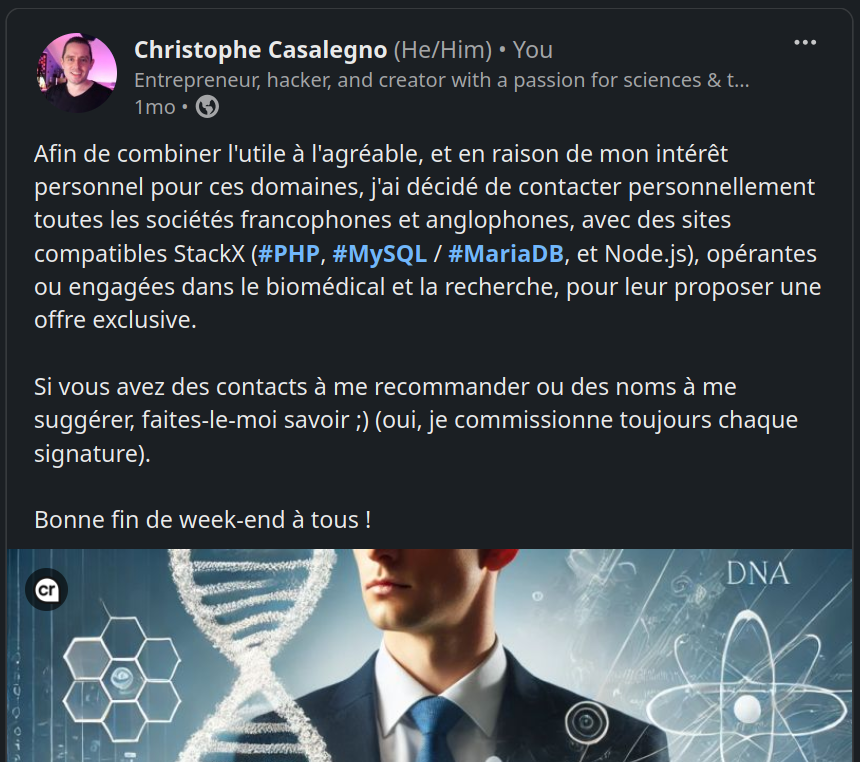
A few days ago, I announced on several networks such as LinkedIn that I was going to contact companies working in scientific fields to offer them an exclusive managed-service offer.
The sales / marketing idea is to systematically "upgrade" the offers to the next level up. I could explain to you why I have a particular personal interest in companies working in this field, but that is another subject :)
To do this, I could start by buying a targeted contact list. However, that would force me to contact far too many companies when only a fraction are actually relevant to this offer.
So here is how I go about it with Bash:
1) I make a local mirror of a specialized online directory that lists a type of company in which I have a commercial interest:
wget --mirror --convert-links --adjust-extension --page-requisites --no-parent --domains monexemple.com https://www.monexemple/
After a quick look at one page, I extract from the whole set of pages the list of links that interested me:
2024-09-22 15:40:45 for i in $(ls) ; do grep -r '<a href="../liens' $i | head -n 1 | cut -d '/' -f2 | cut -d " " -f2 | sed 's/target="_blank">//g' | sed 's/<//g'; done | sort -u > ../../cible1.txt
I then draw up a new list of all those who use the software or the languages that interest me. For example, if I want to obtain the list of all those who use WordPress:
15:54:02-brain@mcp:~/Work/leadscience$ for site in $(cat cible1.txt); do response=$(curl -s "https://$site"); if echo "$response" | grep -q "wp-content"; then echo "$site: OK"; else echo "$site: ERROR"; fi; done > cibleswp.txt
What next? I will probably draw up a list of the hosting services used for each site concerned (host, country, type of offer: server or shared, etc.). A simple whois on the IP addresses will give me most of that information.
Result: with a few lines of commands, I was able to obtain exactly the list of companies that meet my criteria, without wasting resources, nor the time and the money of companies for which this offer would not be relevant (or my own time and money).
Of course, you can do the same thing with your favorite language.
If the subject interests you, tell me in the comments. I would be delighted to share other situations in which I use Bash outside system administration.
I also invite you to tell me your experiences with languages outside their "comfort zone" :) Enjoy the rest of your weekend!
—
Christophe Casalegno
You can follow me on: Telegram | Facebook | LinkedIn | X | YouTube | Twitch

4 comments